In a startup with move-fast lightweight processes:
1. Docs that are naturally versioned with the code, like API doc or a design doc, might well go in the code repos. (I'm personally a big fan of API docs embedded in comment chunks right above the respective implementation chunk, but a separate Markdown or SVG file, or other format, also works.)
2. Everything else, one of the top priorities is to minimize friction to someone who has the information capturing it such that it can be found by someone else later, so put it in the very low-friction wiki (or an issue/task comment).
3. Have a lightweight way of cross-linking things between these locations, that everyone knows, so info is more likely to be found later.
This still applies even if you feed everything into AI now.
Flashback. When I was an adolescent, the dBase and Fox products were my first paid software development, and they were surprisingly accessible to even kids.
I was only supposed to help assemble computer furniture, and maybe install networked Unix and PC software, but the retired Marine my mom worked for thought I had potential. "Hey, Kid", he would say, we need to modify this dBase vehicle fleet insurance database to support more vehicles; figure it out. Here's the manuals for C database library, and Microsoft C, I'm evaluating; figure it out. We need to migrate between accounting systems; here's a sample .DBF of the target schema, here's how you generate a full dump from the legacy minicomputer, use this editor called Emacs to clean up the dump for import, once you figure out the schema mapping; figure it out. I also bought an older dBase product, and then a Fox product, for home, and figured out how to build a few fancier systems.
(Then I kept working, and there was a period when all employers either wanted me to figure out something, or were favorably surprised when I soon did, thanks to formative influences of figure-it-out mentors. Then a break to get belated formal degrees, then being surprised after that pause, when job interviews were suddenly Leetcode-like, and they didn't seem to want me to figure it out, but wanted a rehearsed ritual performance conforming to a big-corporate sanctioned set of rules, and apparently the Marine hadn't written a book to counterbalance that awful green book. :) )
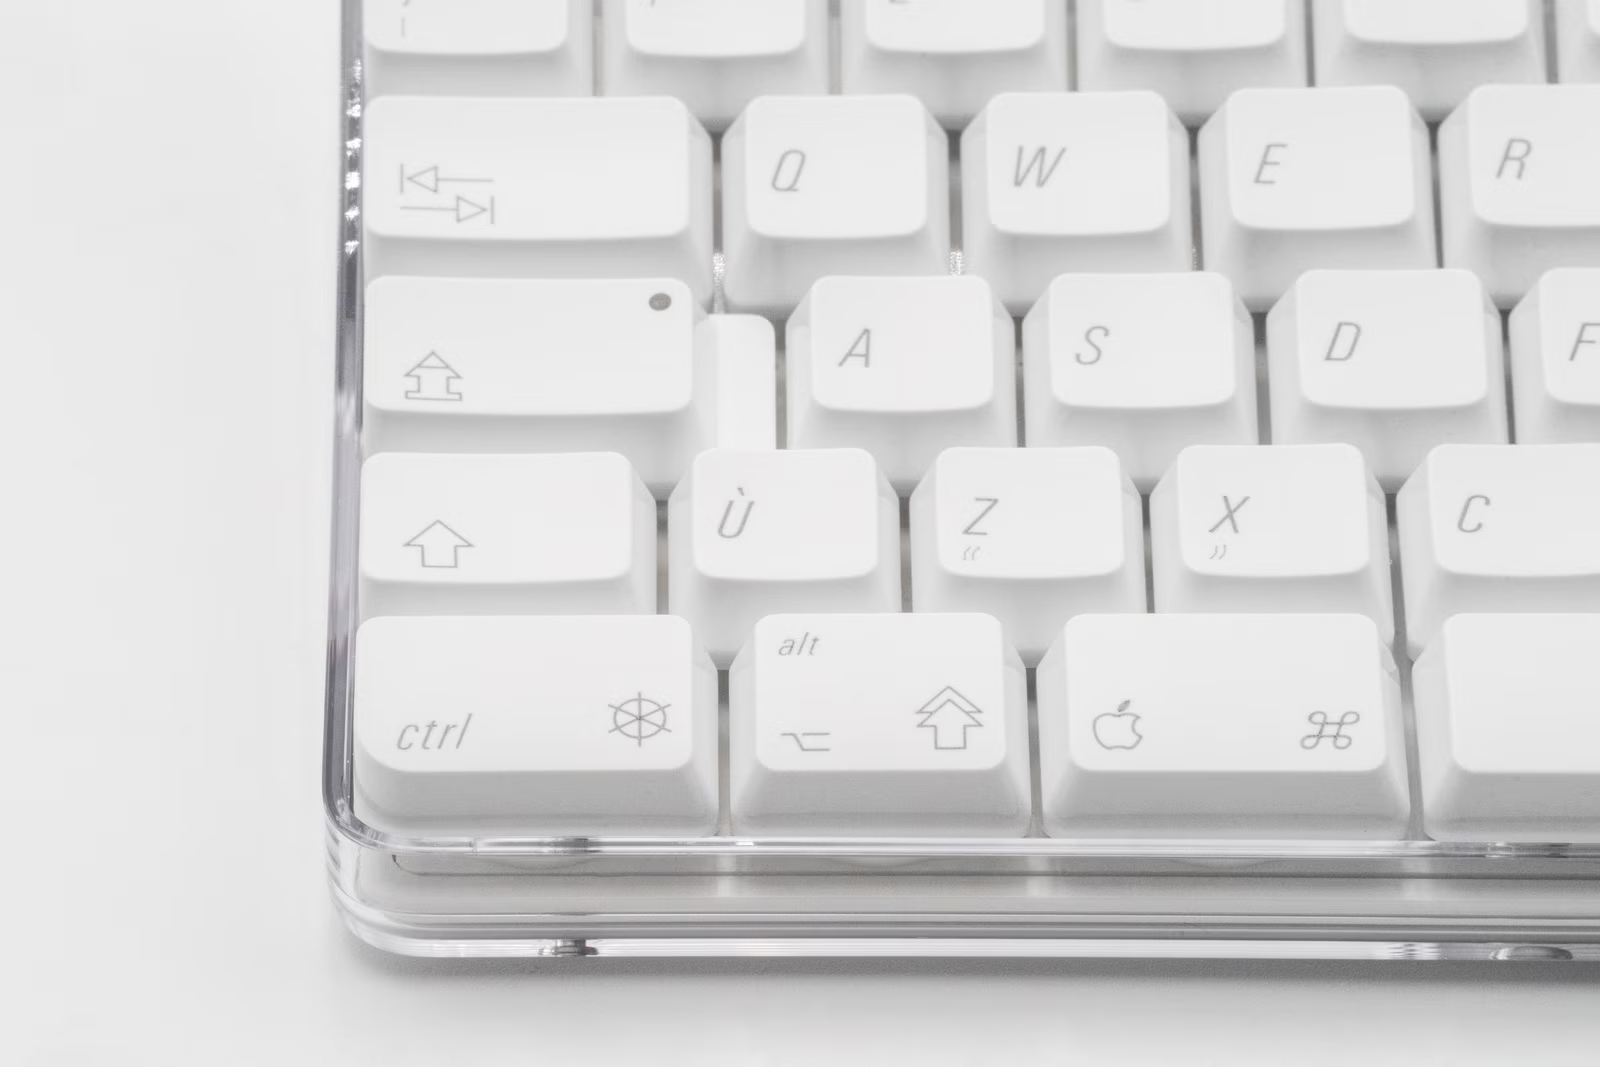
Early Mac design was excellent overall, but decided not to include these keys (maybe they were leaning towards Smalltalk-like context menus?), and then seemed to go into more cryptic and power-user in-the-know keyboard direction (like with the 3-icon key including special support for flipping burgers):
Facebook had a good idea for hiring and retention: pay the highest, and that will boost college students' perceptions of how cool you are.
Facebook got a lot of mileage out of that, running long after public scandals confirmed the early hints of possible sketchiness, back when Google was an attractive alternative.
Though I don't know that's still necessary. The job markets are different now, since there's not many tech employment options that aren't either sketchy or reviled. Anti-AI-worker sentiment seems high lately, outside of HN circles -- much more widespread and negative than I recall any kind of perception of pre-AI tech workers -- yet there aren't a lot of non-AI employment options.
So, some Flock employees might want to leave, over ethics, social status, or company internal culture, but... if they end up at a AI company, they might soon still be seeing a lot of social negative feedback anyway.
("Hi, nice to meet you. ... Me? Oh, I work on, uh, software. ... Yeah, AI is really disrupting things in my field, too. It's been a bit rough, but we're hanging in there.")
Interesting. And all the history of Kafkaesque review interactions that various developers have had could be subpoenaed, as evidence of a pattern: that delays aren't necessarily due to excellence and good faith.
Given the sibling reply, I can imagine them claiming national security prevents them from releasing those records. But that’s okay; I am fairly certain we can find enough developers willing to tell their tales.
Given the short-term pragmatic, conflicted way that AI tech adoption is happening... won't encouraging distillation effectively taint the entire space of open weights models, with the undisclosed biases of a few models that are under the influence of parties (certain billionaires and politicians) known for aggression and duplicity, and not for admirable ethics?
Following news of companies and projects increasingly moving to open weights models.
As AI gets more central to society, we really need to know how the weights were determined.
Open weights isn't just "free as in beer"; it can be "free as in the mystery drug that creepy guy chatting you up at the bar offered you". And maybe even he doesn't even know everything that went into the tablets, since he too was being worked, by an organ-theft ring who will be harvesting both of you tonight.
That's an analogy to get your attention. Your LLM probably isn't going to steal your organs. But in the current environment, it does and will have ideological biases determined by those with direct and indirect influence over it. And there will be a massive market for commercial influence biases (look at how previous generations of adtech invaded almost all technology companies). And there's incentive for military and spying capabilities to be buried in the models, perhaps as long-term sleepers. Maybe some organized crime trojans, too, depending which model you pick up.
In this low-trust environment of the current real world, we need genuine open source models, not closed "open weights", and not mindlessly distilling black boxes gifted by sketchy powerful interests.
It's a good analogy that's probably occurred independently to a lot of us. Here's my version from a private email a few weeks ago:
> [...] I don't like the "great equalizer" effect. [...] Like a kung-fu expert who wandered into a wild-west saloon of drunks all packing six-shooters. (I'm still working on this metaphor.)
Might as well share the entire off-the-cuff email, replying to a great software engineer friend who recently went academic, when they asked what I thought about AI development.
> "You're absolutely right," as the chatbots say.
> I think Claude Code (which I think is currently regarded as the best brand for software development) is for banging out *something* when you don't care so much about the quality. Like most applications of generative AI (homework cheating, customer service, usual corporate ticket-closing).
> And I'm definitely not thinking through the problem very well. The first time I noticed this was on UI design, where Claude would emit a generic *something*, and then the mode is to make incremental tweaks, rather than going through the mental exercises and holistic thinking.
> So sometimes I'm thinking like a non-technical manager, giving initial spec, and then iterating on things I notice -- not thinking like a designer, architect, or engineer.
> Or, like a senior engineer who has to mentor a hyperactive intern who bullshits and plagiarizes like crazy, and makes empty apologies like a sociopath when caught, but is the CEO's nephew, so you can't just fire and blacklist them. You just have to get *something* out of them.
> I can do much better design and better implementation myself, but it's good enough. And it's better than at least half the industry software engineers, so a lot of people who never cared much nor got very good, are in trouble. And management is often a poor judge of skill, if they even care.
> Besides the questions of its performance and utility, and all the ethics questions, I don't like the "great equalizer" effect. Now a lot more people can do (or seem to do) many of things I can do. And I'm having a lot of trouble job-hunting, and companies mostly want people to be using or building AI. Hence learning the robo-plagiarism tools. Like a kung-fu expert who wandered into a wild-west saloon of drunks all packing six-shooters. (I'm still working on this metaphor.)
That conversation might've started when I showed friend my new gen-AI portfolio site, so the context would be realist assessment and handling it, spoken to someone who already knows I'm an enthusiastic hardcore engineer.
(The double exclamation marks in the name drove me away initially, so I tried 3 others first, none of which worked well on the iPhone for my edits, but then "Go Map!!" seemed to just work.)
For edits that can be done from desktop, the OSM official Web site's editor was pretty good -- complicated, but seems to work, and has a nice interactive tutorial mode.


1. Docs that are naturally versioned with the code, like API doc or a design doc, might well go in the code repos. (I'm personally a big fan of API docs embedded in comment chunks right above the respective implementation chunk, but a separate Markdown or SVG file, or other format, also works.)
2. Everything else, one of the top priorities is to minimize friction to someone who has the information capturing it such that it can be found by someone else later, so put it in the very low-friction wiki (or an issue/task comment).
3. Have a lightweight way of cross-linking things between these locations, that everyone knows, so info is more likely to be found later.
This still applies even if you feed everything into AI now.
reply